Overview
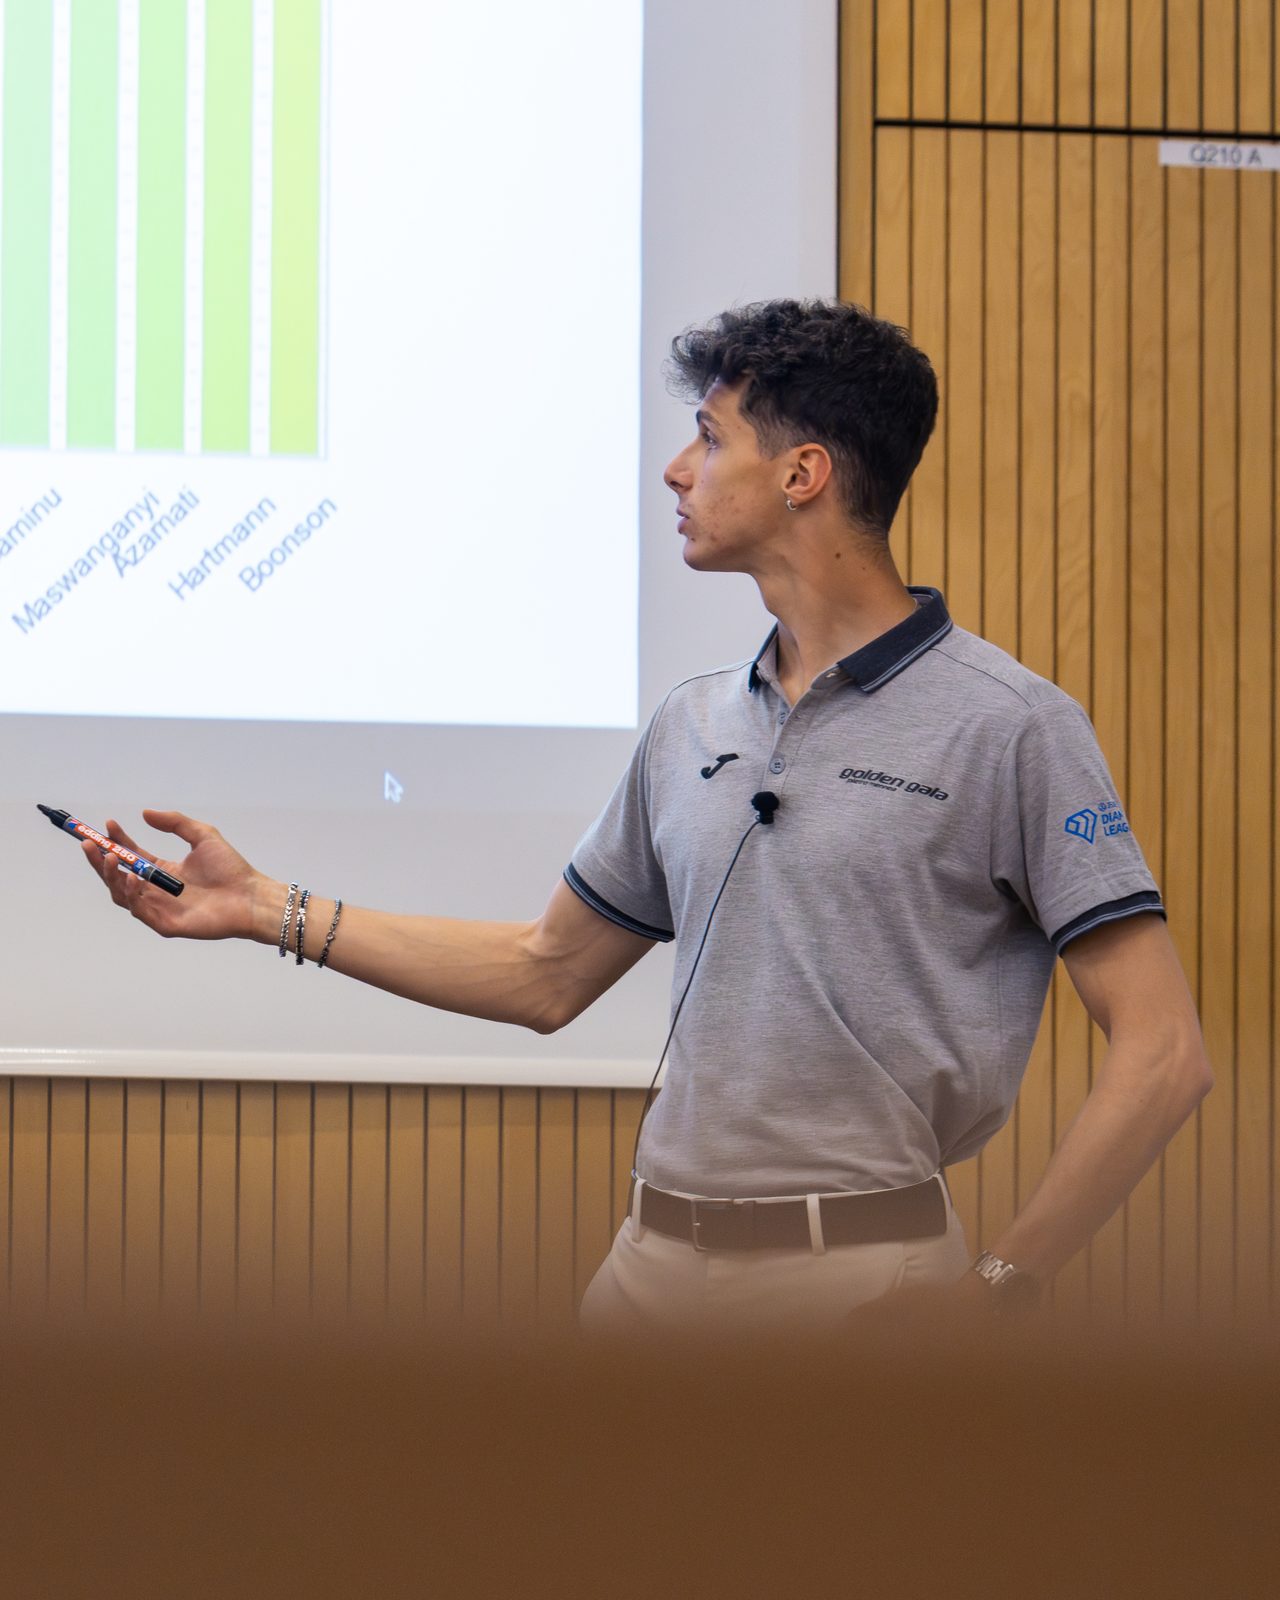
At USI's Digicamp 2025 I taught “Introduction to Sport Analytics” to a class of university students, built around athletics performance data.
Students went from raw race results to a working predictive model: data cleaning, visualisation, reading performance trends and a basic regression model for 100 m results.
What we built
- The full course material as Jupyter notebooks.
- A statistical and regression model predicting 100 m results from seasonal trends.
From the notebook
Read-only · outputs from digicamp-2025.ipynb
Four cells from the class: load a season of 100 m results, normalise them for wind, rank the semifinalists with a heuristic model, then let a linear regression guess the Olympic final. Press Run on each one.
In [ ]:
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt

dataset = pd.read_csv("AthletesDataset.csv", delimiter=",", header=0)
print(dataset.head(8))
In [ ]:
# Wind never stops being a variable: normalise every mark to 0.0 m/s
def normalize_wind_result(row):
    t, w = row["Result"], row["Wind"]
    return t - (0.0449 * w) + (0.009459 * t * w) - (0.0042 * w ** 2)

dataset["Time_Norm"] = dataset.apply(normalize_wind_result, axis=1)

szn = dataset[(dataset["Date"] >= "2024-01-01") & (dataset["Date"] < "2024-08-04")]
SB = szn.groupby("Surname")["Result"].min().reset_index().sort_values("Result")

sns.barplot(data=SB, x="Surname", y="Season_Best", hue="Surname", palette="viridis")
plt.title("Season Best 100m per Athlete (by Surname)")
plt.show()
In [ ]:
# A heuristic ranking model: fixed weights, no learning
features_table["Score"] = (
    0.4 * features_table["Normalized_SB"] +
    0.3 * features_table["Mean_Time"] +
    0.3 * features_table["Recent_Form"]
)

ranked = features_table.sort_values("Score").reset_index(drop=True)
qualified_names = ranked.head(8)["Surname"].tolist()
…
print("\nQualified for the final")
for _, row in ranked.head(8).iterrows():
    print(f"{row['Surname']} ({row['Score']:.3f})")
In [ ]:
from sklearn.linear_model import LinearRegression

lr_model = LinearRegression()
lr_model.fit(X_train, y_train)
final_input["LR_Pred"] = lr_model.predict(X_test).round(3)

for _, row in final_input.sort_values("LR_Pred").iterrows():
    print(f"{row['Surname']:<15} {row['LR_Pred']:.2f} s")